Another thing is. What’s the prior chance that given any bag you see, it is a fake. You may run into same issue for cancer diagnosis. So you ultimately may want F1, precision, and recall, in addition to accuracy. This may also vary from region to region. If you visit China, it may be much higher than in the US/Canada.
I just posted the notebook with 95% accuracy of the CamVid-Tiramisu dataset to my github.
I also included a notebook showing how I converted the labels of the CamVid dataset to match the labels the Tiramisu paper used, and some other training I did.
This is the first personal project I’ve shared. Any feedback about my project and/or github is welcome 
1 Like
My post on how to create a Web App on Render from a fastai v1 model (thanks to @anurag for this possibility) with a focus on local testing before online deployment (for the occasion, I’ve reloaded an ImageNet classifier).
9 Likes
yes that’s what i meant
Hi - first post here. In the spirit of sharing “also the small things”, I’m just putting my web scraper code for Wikipedia here: https://github.com/NicolasNeubauer/fastai-stuff/blob/master/scrape_wikipedia.ipynb
If you find a table containing image references and a column you want to use as a label, you can just use this code, adapt the extraction code, and it’ll write this into a “from_folder”-friendly format.
edit: wrote this before watching the 2nd video; obviously could use more fastai-internal tools.
1 Like
Nice work @pierreguillou. I think I’ll borrow your idea of documenting and testing locally before deploying on Render and update the deployment guide.
1 Like
Yes, I framed it as a classification problem as opposed to a regression or object detection problem. I wanted to see if it was possible to distinguish between different classes of images when those images were composed of things with identical features (eg. all circles).
I played around with repeating this as a regression problem and noticed that it didn’t seem to generalize beyond the ranges on which is was trained. For example, instead of limiting the number of elements from 45-50, I tried using a range of 1-50 and optimizing over the mean squared error.
While this worked very well for images within the range of 1-50, it didn’t generalize very well outside of it. The network would estimate values much, much higher for counts it had never seen before.
Both of these approaches are probably not ideal for “counting” and something like object detection would probably make more sense, but I wanted to play around with edge cases of convolutional neural networks in order to try to learn new things about them.
1 Like
That’s very interesting, I assumed you have also regularized it with weight decay or dropout. If it always overestimate if data is higher than the upper range, you can experiment with predicting log(count) instead of count, or other transform, and see if it will do better. The hunch also comes from the fact that u r predicting a float with regression, and count is an integer. This is making it hard for your CNN.
1 Like
In addition, I didn’t check your notebook in full. Just curious if you can generate an input such that it predicts a negative count. I mention this cos you may want to build in a design, such that nonsense like this won’t happen. And doing log or exp or whatever may make that happen.
Yes those are all good suggestions. With the naive approach I used you can definitely generate nonsense. When I trained for only a portion of the range (10-50) providing low counts like 1 or 2 resulted in negative numbers.
Thanks Jeremy !
Thanks Jeremy. I’ve watched Lesson 2 now, and I think I now have a better understanding of what’s going on. I played around with the model some more, until I got the training loss to be lower than the validation loss, and was able to improve the accuracy significantly (from 12.5% error rate to 5.6%)
Here is a classifier I could build and deploy even before I finished Lessons 1 and 2. This demonstrates the effectiveness of Jeremy’s and Rachel’s methods and the how practical they are.
I am a professional photographer and I take photos of the interior of houses being listed for sale. The number of photos can range from 40 to 100 depending on the size of the house. After taking the photos I need to label them before delivery to my customers.
A sample is below
Photos: https://silverscreen.smugmug.com/Real-Estate/17050-Saint-Anne-Ln/
Virtual tour which needs labelling https://silver-screen-photography.seehouseat.com/1215335?a=1
Labeling photos is a tedious task. So I decided to build a classifier to do it.
I used downloaded images from Google and the classifier can classify images into 7 classes - bedrooms, bathrooms, front views, backyards, living rooms, kitchen and dining rooms.
The notebook is at https://github.com/suresh-subramaniam/fastai
I have not implemented the code to label the photo with the predicted category or created an application out of it. I plan to do it in the future.
I learnt the following
- It is easier to use a Chrome plugin to download photos from Google than the script suggested by Jeremy.
- The best accuracy I could get is around 83%. I had not cleaned the photos before training. I am sure that cleaning up the junk photos will improve the accuracy.
- Sometimes photos of rooms do not have furniture in them. It is harder or impossible to distinguish between a living room and a bedroom, if they both don’t have furniture. This uncertainty is reflected in the low accuracy.
I hope this was useful.
2 Likes
I would suggest just use the last fully connected layer as the feature and don’t process it using PCA.
I see. So you really did get negative counts quite easily just like that. I think you can use your work as a testing ground or study case, for the efficacy of imposing constraints on your predicted outputs to fall on a required domain, to improve overall performance. There seemed to be some calls that this is true. But i don’t know.
In your case, you want to avoid negative. A log(count) or log(count + 1) can achieve this since you will need to do exp(your prediction) to get back the real count, and exp(x) is always > 0.
Also, it may be more revealing if you make your validation set a bit tougher, e.g.
Train: Use synthetic image with 1-10 circles
Validation: Use synthetic image with 1-15 circles.
Now, if your network is not generalizable, you will catch it early. Your validation error will never approach to where you like it. But if you are doing very well even with that, then thats onto something. Then you have more hope it can generalize outside of these ranges in your final test set.
In general, it actually maybe good to sneak in some “tough” sample to the validation set, maybe even tougher than the test set (speculate it if you can’t see it), to challenge your model.
1 Like
Nice work, rastringer. This is one of the ideas I considered taking up, glad to see someone did it. Out of curiosity, do you train either one? I’ve been training bjj for about 15 years now, and have dabbled in judo.
It would be interesting to see how a classifier would do with neutral poses, since there are subtle differences in the way the gi is worn. The classic judo gi is slightly looser fitting and longer than in bjj. Bjj practitioners are also a more liberal with their patches than judo.
thanks for the suggestion @maral the idea behind using PCA is to speedup the similarity calculation, so instead of a feature vector of 512 per image I will end up with smaller vector (says dozen). Also PCA should be good at capturing most of the information in this new space. I think the problem is with the dataset, may be if I try with another one I could end up with more interesting paths.
Yes, you are welcome to do so @anurag. Testing locally saved me a lot of time, helped me better understand your files and allowed me to customize html, css, js and server.py files.
Hello,
I have created a basic ship identifier by training on the images downloaded using googleimagesdownload. I made this after completing the first lesson. The accuracy is very poor, due to lack of data (I think) I would really like some suggestions on it. Here is the gist of it.
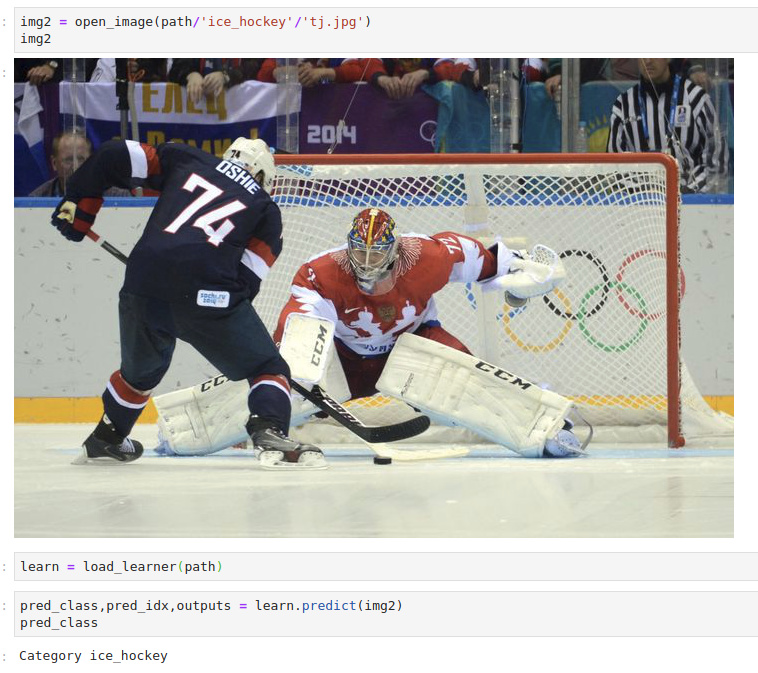
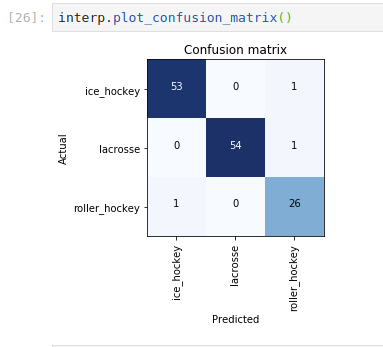
After lesson 1 I built a classifier to try to predict the difference between inline/roller hockey, ice hockey, and lacrosse. I figured it would do well with lacrosse, but I was honestly surprised at how well it did predicting ice hockey vs. roller hockey. The final error rate was .022.
Here are two final pictures I gave it that it had not seen before: