I’m not sure which url you are talking about. If you are talking about the hackathon url then it’s here. I downloaded the data from analytics vidhya and uploaded it on Kaggle here. You can directly go to this link and select “New kernel” or you can fork my kernel and execute the code.
1 Like
Hi,
Nice to see someone working on the same dataset (HAM10000 contains the same dataI believe)! Just like you I see the validation loss sometimes going through the roof. Not sure how to interpret this, I made the assumption I put the wrong learning rate, but maybe this is not correct.
Did you pay any special attention to the class imbalance during the training? Or just run a lot of epochs? So far I got to an error rate of about 0.09, didn’t get to the balanced accuracy score yet.
Back at ya! I’m glad to see someone working on the HAM10000 dataset. I did have some issues with the validation loss on the 299x299 but I think that could be improved by using the weight decay tester but I was just getting a really good result with the 128x128 so I kind of stopped there. However, even with the 94% accuracy on the holdout set (and 89% accuracy on their validation set of which there is no ground truth), when I submitted to the competition, I got a 0.69 accuracy which didn’t make sense because for their set validation score to be 89% and then the test to be 0.69 just didn’t make any sense to me.
I’m assuming it’s something I haven’t accounted for in my model (and I’d really welcome anyones advice on that).
And to answer your question, it was mostly just running a lot of epochs and fine tuning the learning rate as I went along. If you’re not using weight decay, I would use it cause it really helped my model a bunch.
i was talking about the dataset as the uploading speed at my place is not good …and thanks for the upload did you try to increase your accuracy??
Hi Danny,
One of the things I noted is that you run the model on a very small validation set: 5%. If you run > 16 epochs with such a small subset, you risk overfitting on the training data and ‘luck’ that the validation set suits the training set.
Maybe I misinterpret your approach, but if the above is true, then consider a validation set of at least 20% of the data, try different seeds as well.
Hi all! I’ve created a classifier to detect different kinds of insects: https://insects.space (sorry, it’s in Russian  ).
I’m getting good 99% accuracy on a dataset from Google Images (around 400 pics per class) but still when I add totally new pictures it sometimes gives wrong results. Assuming I need to add more classes and use bigger datasets for training.
2 Likes
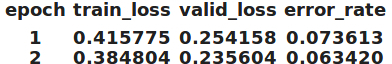
Thanks to this great forum I created a Cuneiform classifier, that can distinguish between 50 logographs with 6.3% error (and I’m sure it can be improved)
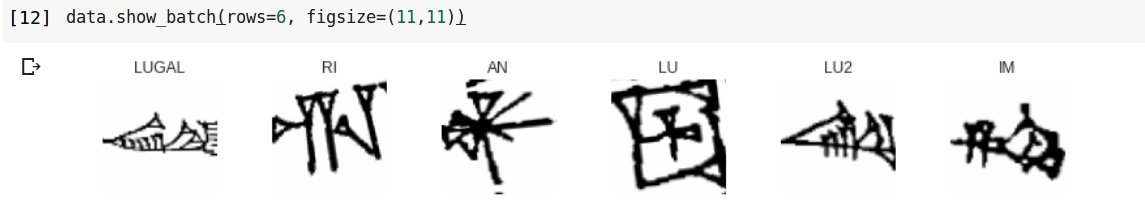
Also most_confused() made a lot of sense. Check out LUGAL and LU2 from show_batch()… In Sumerian ‘LU2’ is man and LUGAL is king (great man)
3 Likes
David,
I did at one point try a validation set of just 5% just to see what happened however, I’ll look through my code again and clean that up if I left it in there and make a note.
Not sure if you’ve posted (or are willing to) but I’d be interested to see your approach if you have and see what the differences are. Either way, thanks for the heads up on the random seed, I’ll see what that does, I hadn’t thought of that
This is a cool use case. For speeding up predictions, I wonder if it would work to predict a 9x9x9 tensor where hight/width correspond to the 9x9 sudoku grid, and the channels correspond to class predictions for 1-9. Then you would just take the argmax along the channel dimension to get your full sudoku grid.
This has the disadvantage of predicting on digits that are already given, but it has the advantage of predicting any 9x9 sudoku grid in one pass.
Would like to share a “gotcha”.
If you let the data bunch do the random split into train/val set for you (just like in lesson 1), be careful about the random seed. I saw my resnet50 error rate dropped all the way to ~1% (99% accuracy) just doing this
- save model
- quit notebook
- bring back notebook and
- run the data bunch only for the resnet50 version.
- load model
- train for 1 epoch
I know enuf i screwed up immediately seeing that sudden drop for not doing much. I determined that i skipped resnet34 one this time, so the random seeding is altered when i created the data bunch is giving me a different split on train/validation. Now, my model is effectively getting trained on more data, and validating on some data it has seen before.
If you see something wrong with what I said, pls feel free to correct me. Won’t mind that at all. If you ever seen something like that in your own work, pls share and corroborate.
3 Likes
Hi karan, I did not. I tried resnet50 with larger size images but my kernel was crashing I think. After that, I have been busy with other things. But you can certainly give it a try and let me know if you get good results. Also let me know if you come across any other interesting hackathons. Cheers.
All -
I created a basic template of using fastai for the Petfinder Kaggle Competition going on. The code is setup to use fastai tabular and is end-to-end from processing all the given data to creating the submission file for evaluation. The results aren’t too great (yet) but this is just a naive implementation with almost no feature engineering. Let me know if anyone wants to collaborate and I can add you to the kernel.
https://www.kaggle.com/deepbilal/using-fastai-tabular-on-petfinder
Cheers,
This is awesome - where’s the twitterbot?
Cool. Looks like Kaggle is under maintainance now? Will promise to take a look when it comes back.
1 Like
Hello alvisanovari,
How do you get the data,Can you share it?Thks
IMDB-Wiki Database: https://data.vision.ee.ethz.ch/cvl/rrothe/imdb-wiki/
Thanks:狞笑:
Hey … i am working on a project where in i want to create a prototype on a microcontroller that will be attached on a buggy robot with a camera to detect road traffic signs and alert the driver on the upcoming signs …i trained my model on GTSRB (german road sign dataset) and got pretty hogh accuracy with 42 different signs…now i want to do object detection on road sign…thats my first doubt…then can rasberry pi do the image processing,detection,classification
?? and lastly how to proceed form here…i used pretrained resnet architecture and now how to deploy it on rasberry or any other microcontroller???
thank you
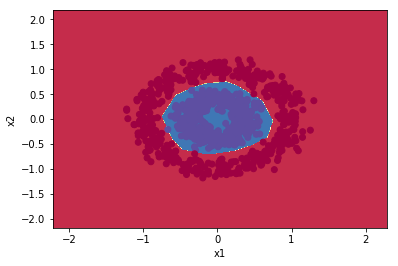
If you ever wanted to dive deeper into the actual implementation of neural networks without jumping from one PyTorch definition to the other, see numpy-dnn. I’ve spent some time putting the basic building blocks of convolutional neural networks into one single place. This repo shows how to write neural networks in a modular way, calculate gradients, and automatically check whether the network has been built properly. Plus this vectorized NumPy implementation works amazingly fast. If you’ve got new ideas or want to add support, e.g., for RNNs and GPU, you are welcome to contribute!
7 Likes
Hi @jeremy and everyone!
I was working on an assignment and I published the same as a Kaggle Kernel. It’s a multiclass food classification problem using FOOD-101 dataset which has 101 classes of food. Since it takes too long to train on all 101 classes, I trained the model on 3 classes first and then trained on 11 classes separately to validate and confirm that the model does well even with more number of classes.
The first model trained on 3 classes can classify apple_pie / pizza / omelette. As I was experimenting with different inputs, I gave the model an image which has both applie pie and pizza.

What I noticed was, when the objects in image are flipped vertically, the model changed its output classification from one class to another.
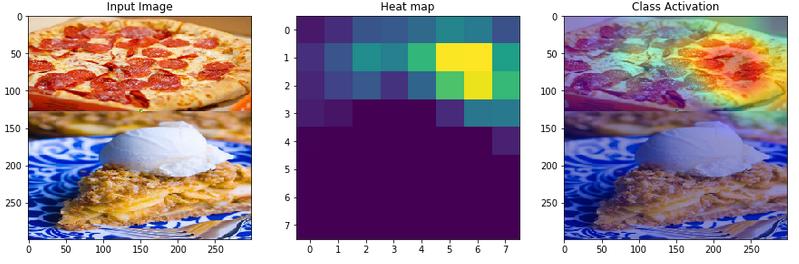
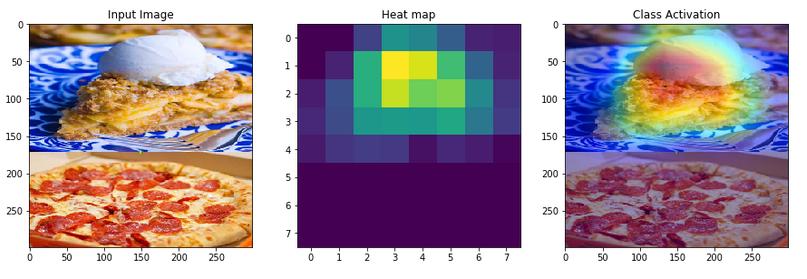
I tried the same with horizontal flip. In this case, the model gave the same output and also with almost similar confidence(92% vs 90%)
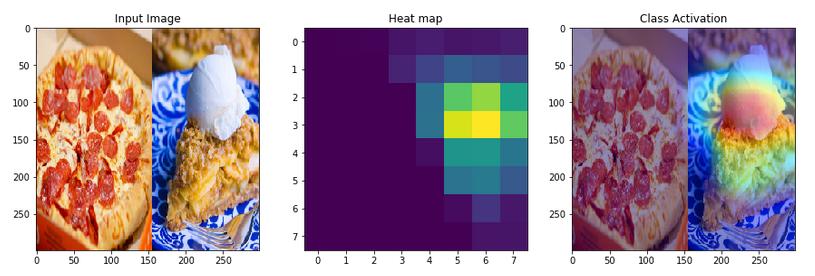
I am yet to try this with more images and from different classes. I am curious to know what the reason could be in both cases where the model flipped its output for vertical flip and gave out the same class for a horizontal flip.
Here’s the kernel - https://www.kaggle.com/theimgclist/multiclass-food-classification-using-tensorflow
Note - I used TensorFlow and Keras for this assignment.
Thanks,
1 Like